The Multiplayer Launch Day Problem: Planning for Demand You Cannot Predict
Prepare for unpredictable launch-day demand with flexible game-server infrastructure that scales across regions without wasting money on idle capacity.
Launching a multiplayer game creates an awkward infrastructure problem: you need to prepare for demand before you know what that demand will be.
Wishlists, beta registrations and pre-orders can all provide useful signals, but none of them gives you a reliable picture of launch-day concurrency. A streamer might send thousands of players towards one region in a few minutes. A quiet launch can accelerate after a clip spreads on social media. Demand may peak at different times across Europe, North America and Asia, while one playlist becomes far more popular than expected.
Good multiplayer game launch infrastructure is not built around predicting one perfect number. It is built to respond when the number is wrong.
Launch demand is not one number
Studios often discuss launch capacity as a single target: how many concurrent players can we support?
That number matters, but it hides the operational detail. Players do not arrive evenly. They arrive in groups, in particular regions, on different platforms and with preferences for different modes. Their sessions may last ten minutes or three hours. Some will sit in menus, some will queue repeatedly and others will reconnect after a failed attempt.
The infrastructure requirement is shaped by all of that behaviour.
A co-operative title with four-player sessions creates a different allocation pattern from a 100-player battle royale. A persistent survival game may keep servers alive for days, while a round-based shooter can return capacity to the available pool after each match. Two games with the same peak concurrency can therefore need very different numbers of servers and very different scaling strategies.
Instead of producing one forecast, build several operating ranges:
A conservative baseline based on the audience you are confident will arrive.
A realistic high case based on strong launch performance.
A breakout case covering influencer traffic, unexpected press or rapid social growth.
Model each range by region, match type and time of day. The purpose is not to guess the future perfectly. It is to expose where capacity needs to expand, how quickly it must become available and what the player experience should be while it does.
Replace static capacity with an elastic fleet
Permanent launch capacity can feel reassuring. It can also leave a studio paying for a large number of empty servers once the initial peak passes.
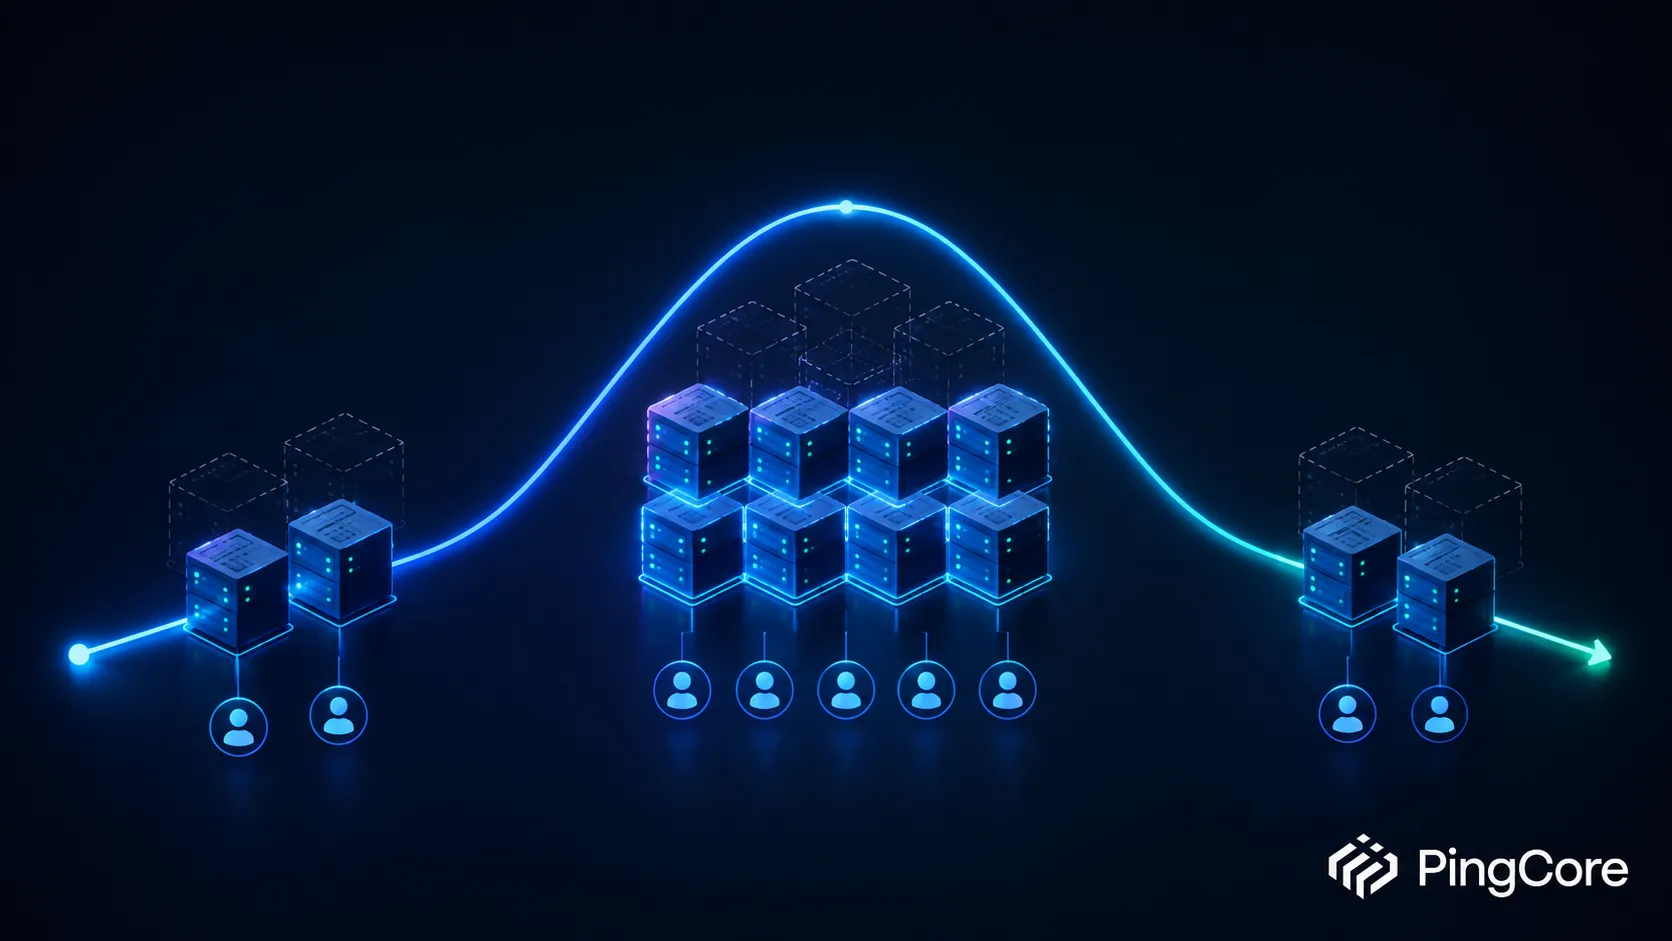
An elastic fleet uses several layers of capacity instead:
A minimum regional floor that is ready for normal demand.
A warm buffer that can absorb short bursts without making players wait for new instances.
Dynamic capacity that scales up as demand grows.
A tested ceiling that protects budgets and prevents uncontrolled expansion.
The balance matters. Keep too much warm capacity and the studio pays for servers nobody is using. Keep too little and every spike becomes a race between player patience and server startup time.
Scaling down requires just as much thought as scaling up. Infrastructure should distinguish between an empty available server and one that has already been allocated to a match. It should drain sessions safely, respect persistent data and avoid repeatedly adding and removing capacity when demand moves around a threshold.
The goal is not simply to run fewer servers. It is to keep enough capacity ready for the next group of players while retiring genuinely idle resources.
Scale on player demand, not CPU alone
Traditional infrastructure monitoring tends to focus on CPU and memory. Those metrics remain important, but they rarely describe the complete state of a multiplayer fleet.
A server can show modest CPU use while every available session is full. A region can have plenty of compute capacity but no compatible servers for a particular build or playlist. A queue can grow before infrastructure utilisation looks alarming.
Useful scaling signals include:
The number of players waiting in each regional queue.
The number of ready, allocated and occupied game servers.
Available player slots by game mode and version.
Match creation rate and recent demand growth.
Server startup and readiness time.
Session length and expected server turnover.
Failed allocations, reconnects and abandoned queues.
CPU, memory, network and process health.
No single metric should make every decision. The safest approach combines infrastructure health with actual matchmaking demand.
For example, a growing queue may trigger additional servers before existing machines reach high utilisation. A falling player count may begin a controlled scale-down, but only after empty instances have remained unused for a defined period. This creates a fleet that follows player behaviour without constantly oscillating.
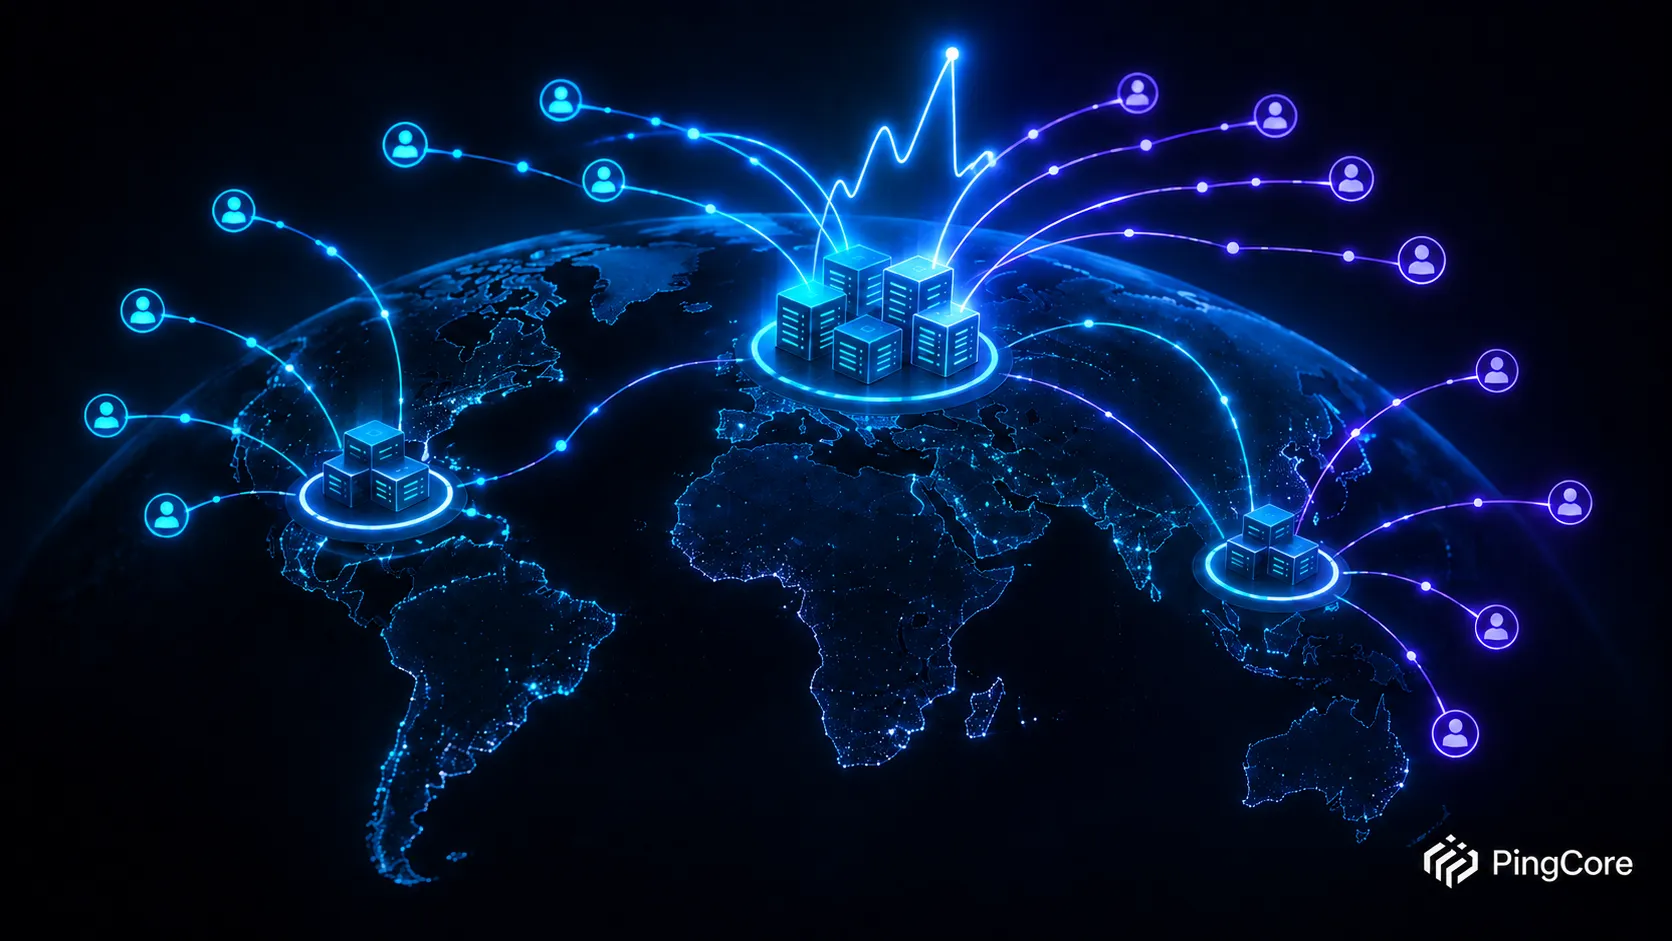
Treat every region as its own launch
A global launch is really several regional launches happening on overlapping schedules.
Marketing activity, platform popularity, local time zones and streamer audiences can create sharp regional differences. Spare capacity in one location does not automatically help players somewhere else if using it would introduce unacceptable latency.
Studios should decide before launch:
Which regions require a permanent minimum fleet.
How much warm capacity each region needs.
Whether neighbouring regions can provide temporary overflow.
What latency increase is acceptable during a surge.
How parties containing players from different regions are placed.
Whether less popular modes can temporarily share wider matchmaking pools.
Deploying from a common configuration reduces the chance that one region behaves differently because of a manual setup error. However, scaling rules can still be tuned by region. A one-size-fits-all threshold is unlikely to reflect the way a real global audience arrives.
Prepare for the influencer spike
Influencer traffic is difficult because it can be both sudden and concentrated. A creator going live may send a large group into the same region and playlist at almost the same moment.
The answer is not necessarily to keep breakout-level capacity running for the entire launch window. It is to shorten the path from signal to server.
Studios can monitor queue growth, allocation rates and player arrivals for early signs of acceleration. Known creator activity can be treated like a scheduled event, with temporary warm capacity added beforehand. For truly unexpected attention, automated scaling should begin before queues become unmanageable, while clear limits protect the studio from runaway cost.
It is also worth planning what happens during the gap between demand appearing and new servers becoming ready. A transparent queue is better than repeated connection failures. Players should retain their place, parties should remain together and the client should avoid sending people towards servers that are still starting.
Plan for successful degradation
Autoscaling is important, but it should not be the only launch protection.
Every platform has limits, and every dependency can fail. Studios need a controlled way to reduce pressure without making the entire game appear broken.
Depending on the game, that might mean:
Temporarily limiting access to non-essential modes.
Pausing custom server creation while protecting active matches.
Widening region or skill preferences with the player's consent.
Applying an admission queue rather than allowing repeated failed requests.
Reducing the frequency of non-critical telemetry or background services.
Keeping authentication, parties and reconnects ahead of lower-priority features.
These decisions should be agreed before launch. They are much harder to make while the team is responding to a live incident.
Rehearse the whole allocation path
A load test that only measures game-server CPU is incomplete. Launch readiness depends on the entire path from a player pressing Play to entering a healthy session.
Test matchmaking, server allocation, container startup, configuration delivery, health checks, network port assignment and the return of the connection address to the client. Confirm that scaling works independently in each target region and that the fleet can recover when instances fail during a surge.
Scale-down behaviour also deserves a rehearsal. Make sure active matches are not terminated, persistent data survives restarts and outdated builds cannot accidentally re-enter the available pool.
Finally, practise a rapid deployment and rollback. Launch-day pressure often exposes a software problem as well as an infrastructure problem, so the team needs a safe way to update server builds without creating a mixed and incompatible fleet.
How PingCore approaches launch-day scaling
PingCore gives studios a Kubernetes-native platform for configuring, deploying and managing dedicated game servers across multiple regions. Fleets can scale up as matchmaking demand grows and scale back down when servers are no longer needed, reducing the need to hold breakout-level capacity permanently.
Studios can configure resources, ports and deployment specifications through the management interface, then automate fleet operations through the REST API. That includes creating deployments, scaling them up or down, querying usage and health, and integrating server allocation with a matchmaker.
PingCore also supports startup, readiness and liveness probes, stateful containers with persistent storage, global deployment and gaming-specific DDoS protection. These capabilities matter on launch day because new capacity must not simply exist. It must start correctly, report itself as healthy and become available to players in the right region.
Usage-based billing aligns the commercial model with an elastic fleet. Rather than treating the largest predicted launch scenario as permanent infrastructure, studios can keep a sensible baseline, expand when demand arrives and remove idle capacity once the peak has passed.
A practical launch infrastructure checklist
Before release, confirm that your team can answer these questions:
How many servers are required for the baseline, realistic high and breakout scenarios?
Have those figures been calculated separately for every launch region and game mode?
Which player and fleet signals cause capacity to scale up?
How long does a new game server take to become genuinely ready for allocation?
How much warm capacity will be maintained in each region?
How are active sessions protected when the fleet scales down?
What happens when a region reaches its capacity ceiling?
Can players queue without losing their party or repeatedly reconnecting?
Can the team see queue depth, server state, failed allocations and regional health in one place?
Has the complete player-to-server path been tested under realistic load?
Can the server build be rolled back safely?
Who can change scaling limits, and how are those changes recorded?
You do not need a perfect forecast
Launch-day planning is not about proving that your player forecast was correct. It is about making sure the infrastructure can respond when reality looks different.
That means preparing capacity by region, maintaining a measured warm buffer, scaling on matchmaking demand and protecting active sessions as the fleet contracts. It also means setting limits, rehearsing failure and giving players a controlled experience during any short period when demand moves faster than infrastructure.
You cannot know exactly how many players will arrive. You can make sure your multiplayer infrastructure is ready to move with them.
If you are preparing a multiplayer launch, explore the PingCore platform or speak to the team about testing a demand-led, multi-region deployment before release.